Chenlu Ye
I am on the job market.I am seeking full-time positions. My interests include self-improving agents, autonomous research, and reinforcement learning for LLMs.View CVEmail me
My research focuses on self-improving agents and autonomous research, reinforcement learning for agentic LLM post-training, and decision-making. I study how agents learn from experience and improve their skills and memory, building on my work in LLM reasoning, RLHF, and robust reinforcement learning.
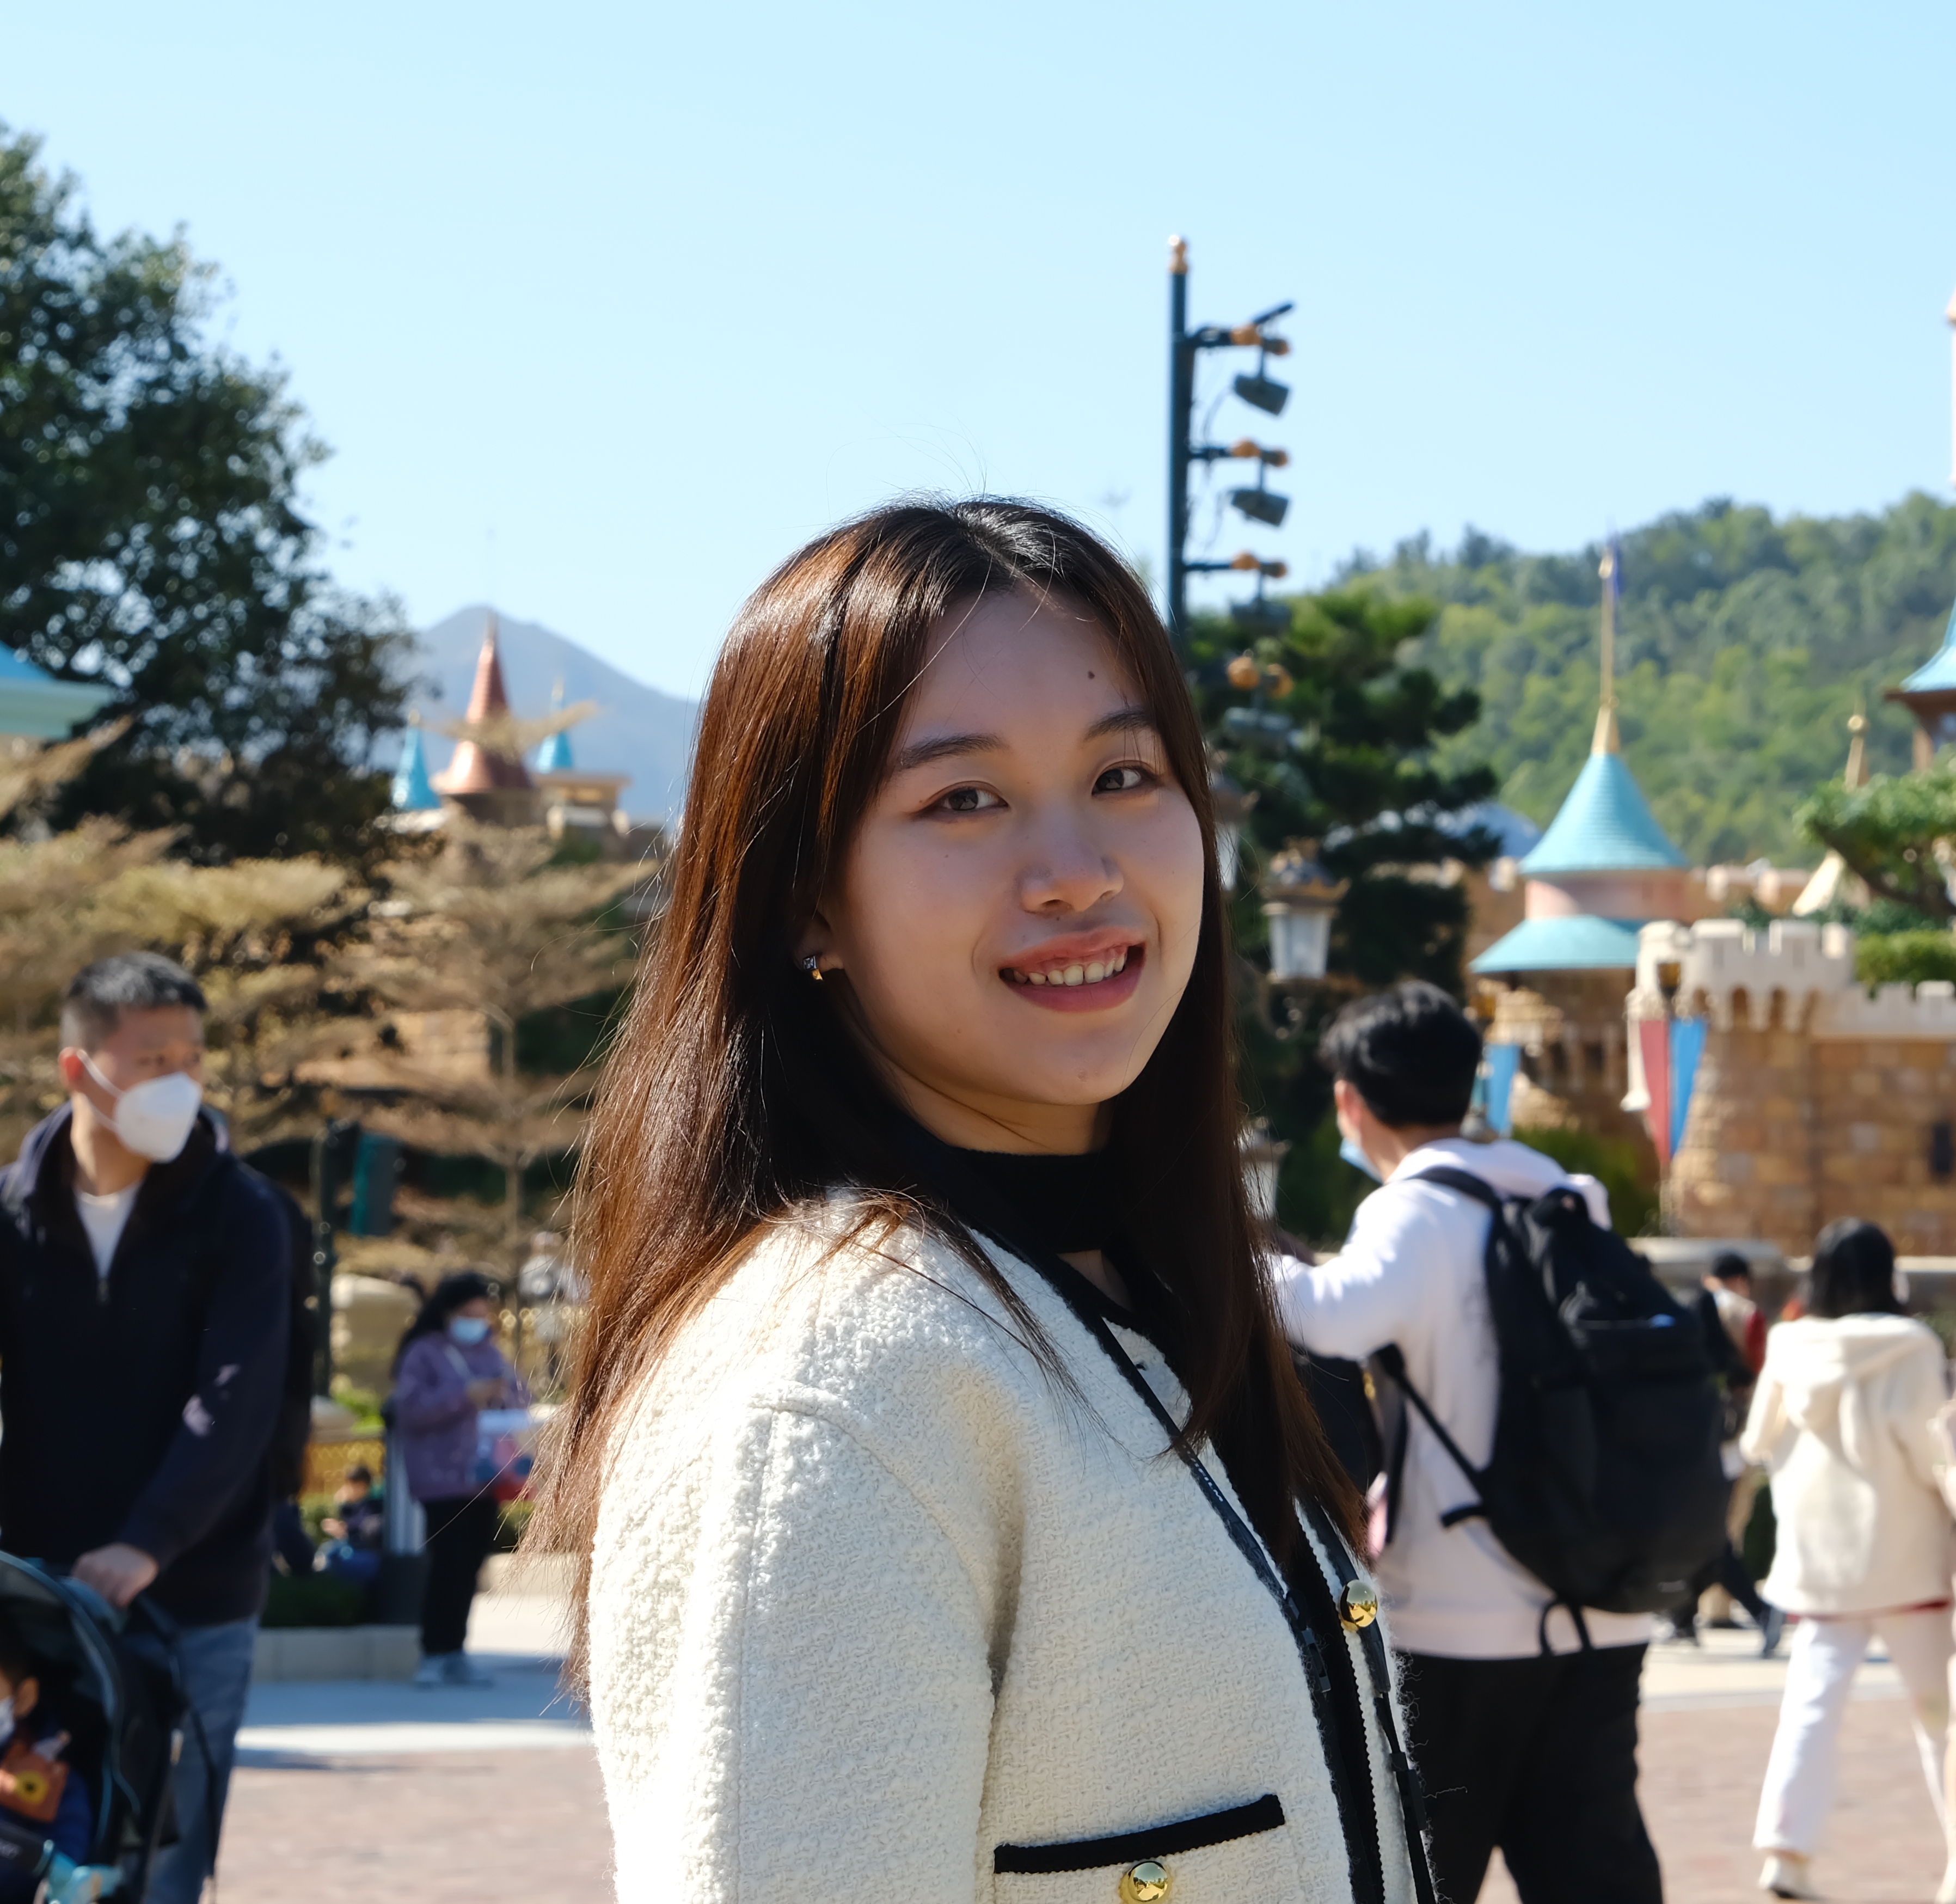
I am currently a research intern at Meta MSL / FAIR, working with Sainbayar Sukhbaatar and Jason Weston. Previously, I was an applied scientist intern at Amazon and received my MPhil from HKUST and B.S. from USTC.
Selected Publications (Full)
* denotes equal contribution.
PreprintAdaptive Layerwise Perturbation: Unifying Off-Policy Corrections for LLM RLPreprintLayerwise policy perturbations for robust off-policy RL under system noise and training-inference mismatch.blogPDFCode
PreprintReinforce-Ada: An Adaptive Sampling Framework under Non-linear RL ObjectivesPreprintAdaptive generation-budget allocation across prompts to preserve informative and diverse RL training signals.PDFCode
PreprintBeyond Correctness: Harmonizing Process and Outcome Rewards through RL TrainingPreprintProcess-outcome consistency for RL data selection, improving final-answer accuracy and intermediate reasoning quality.PDF
PreprintSelf-Rewarding Correction for Mathematical ReasoningPreprintPDF
ICML 2025
SpotlightCatoni Contextual Bandits are Robust to Heavy-tailed RewardsICML 2025 SpotlightPaper
NeurIPS 2024Online Iterative Reinforcement Learning from Human Feedback with General Preference ModelNeurIPS 2024PDFCode
ICML 2024Iterative Preference Learning from Human Feedback: Bridging Theory and Practice for RLHF under KL-ConstraintICML 2024Paper
Experiences
Research Intern, Meta MSL / FAIR (2026.05 - present).
Self-improving agents, skill and memory learning, and compute-efficient training for autonomous research agents.
Managers: Sainbayar Sukhbaatar and Jason Weston.
Applied Scientist Intern, Amazon (2025.05 - 2026.05).
Robust off-policy RL and process-aware training for LLM reasoning, including ALP and PROF.
Hosts: Dr. Zhou Yu and Dr. Ziji Zhang.
Visiting Research Scholar, UCLA (2023.08 - 2023.12).
Corruption-robust reinforcement learning. Host: Prof. Quanquan Gu.
Education
Ph.D. candidate, Computer Science, University of Illinois Urbana-Champaign (2024.08 - present).
Advisor: Prof. Tong Zhang.
MPhil, Artificial Intelligence, The Hong Kong University of Science and Technology (2021.09 - 2024.08).
Advisor: Prof. Tong Zhang.
B.S., Statistics, University of Science and Technology of China (2017.09 - 2021.06).
See my biography for research experience, professional service, and honors, or download my CV.